AI CONTROL PLANE · COMING SOON

Lion AI Cloud

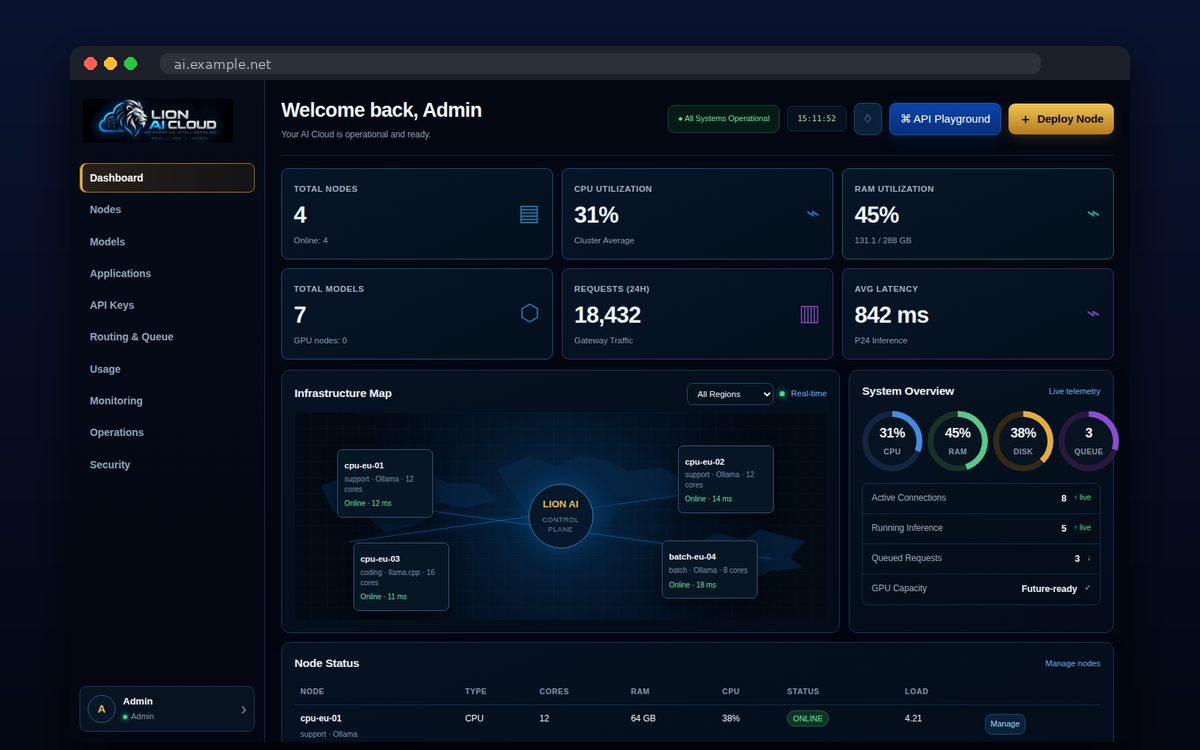
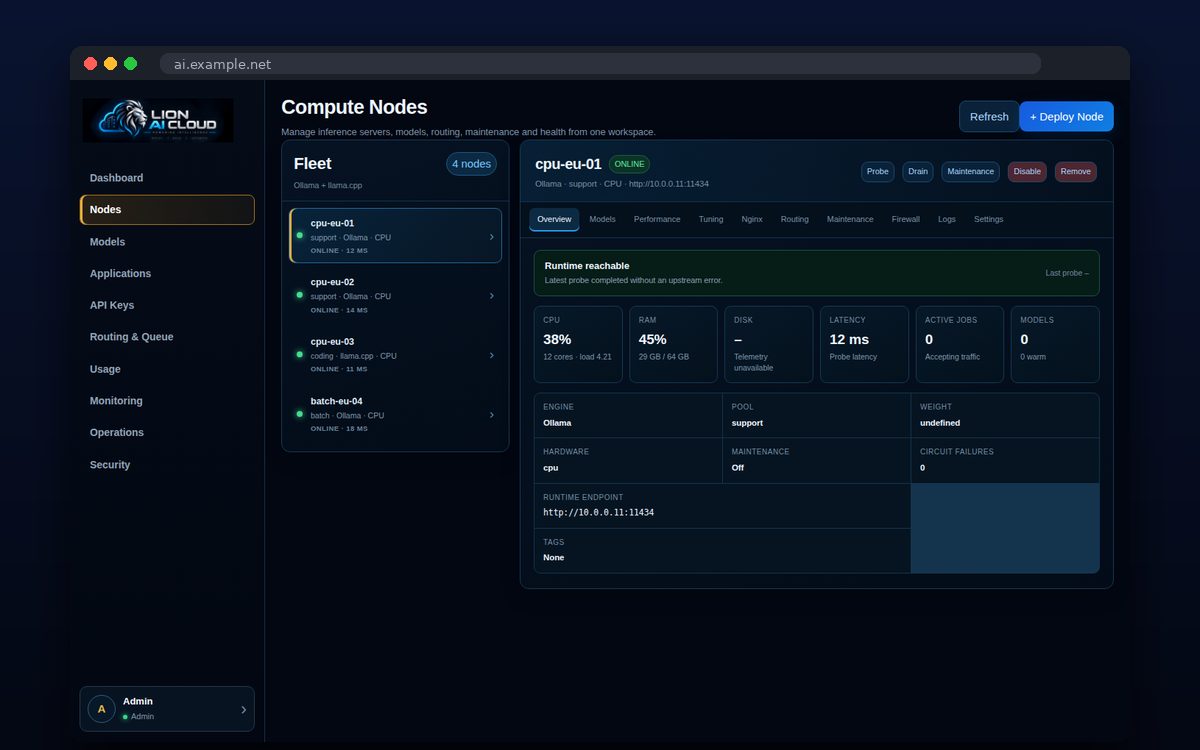
Run your own AI models on your own servers. Lion AI Cloud organises Ollama and llama.cpp nodes behind one gateway with API keys, a queue and monitoring.

Your own models, on your own terms

Lion AI Cloud is the control plane LionHost uses for its own AI tools, such as the WHMCS support assistant. It connects servers running Ollama or llama.cpp and presents them as one gateway.

It is designed first for CPU servers, with no graphics cards required: the scheduler considers each node’s RAM, disk and load, and it is ready for GPU nodes when you need them.

Separate limits for every application

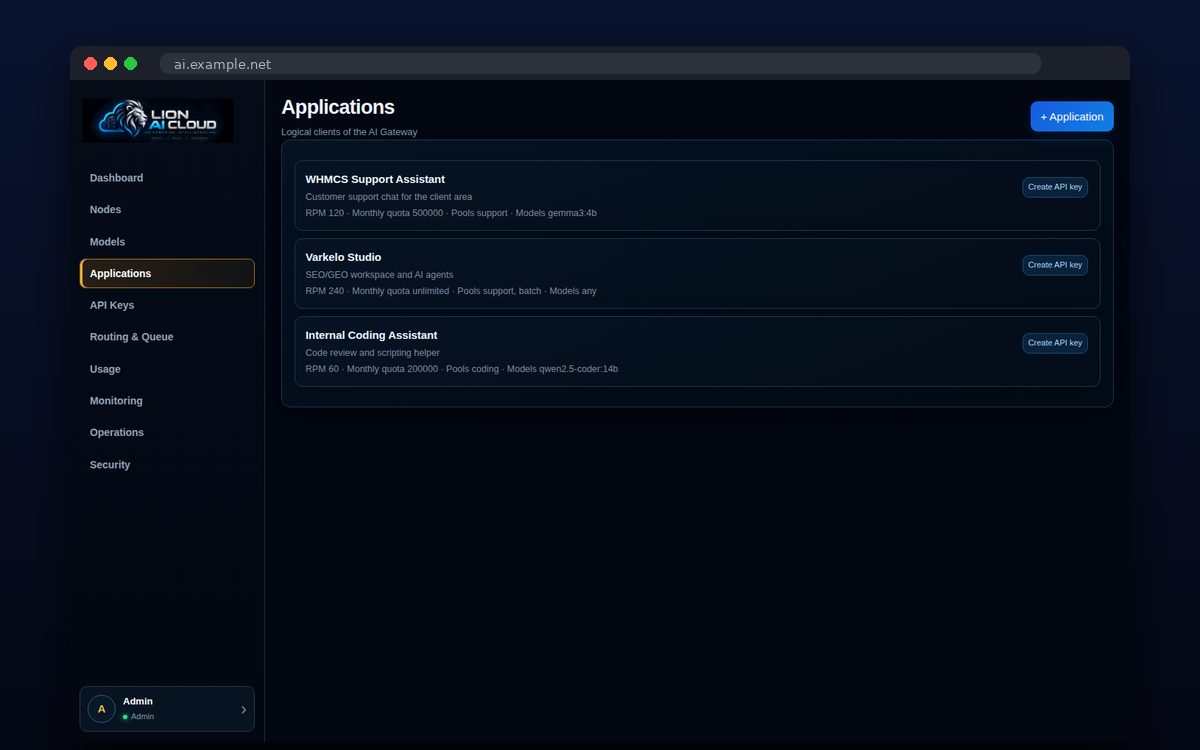
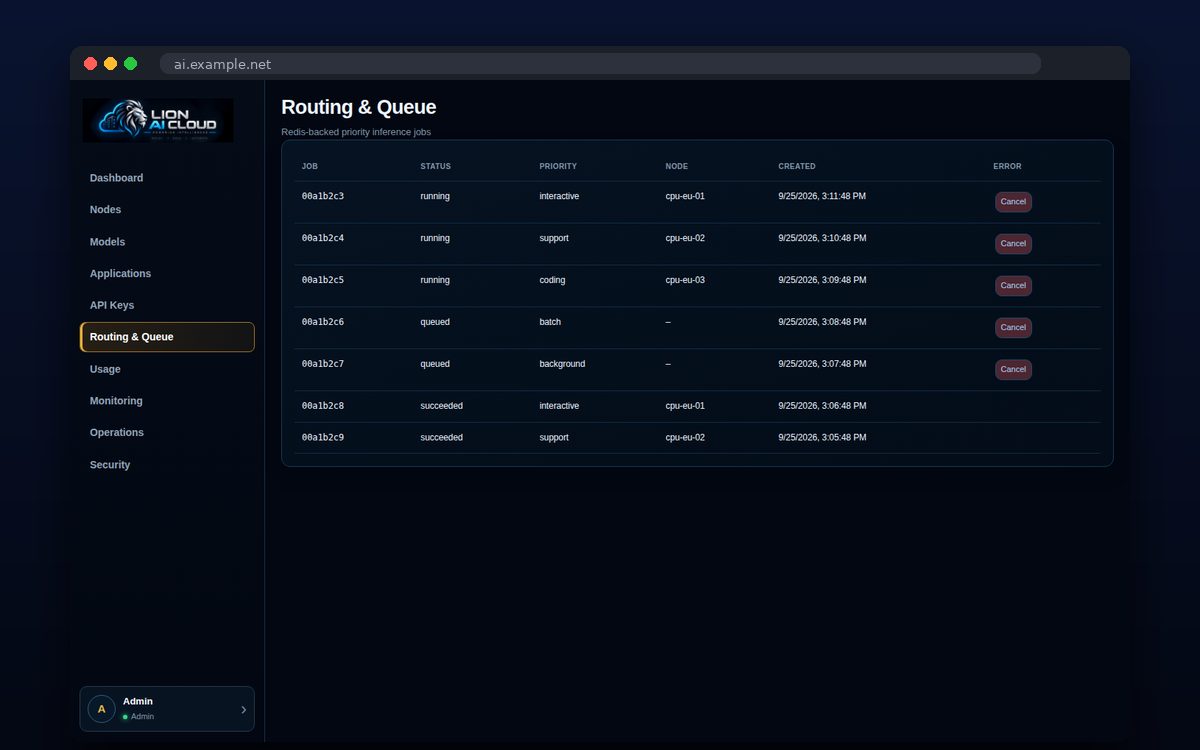
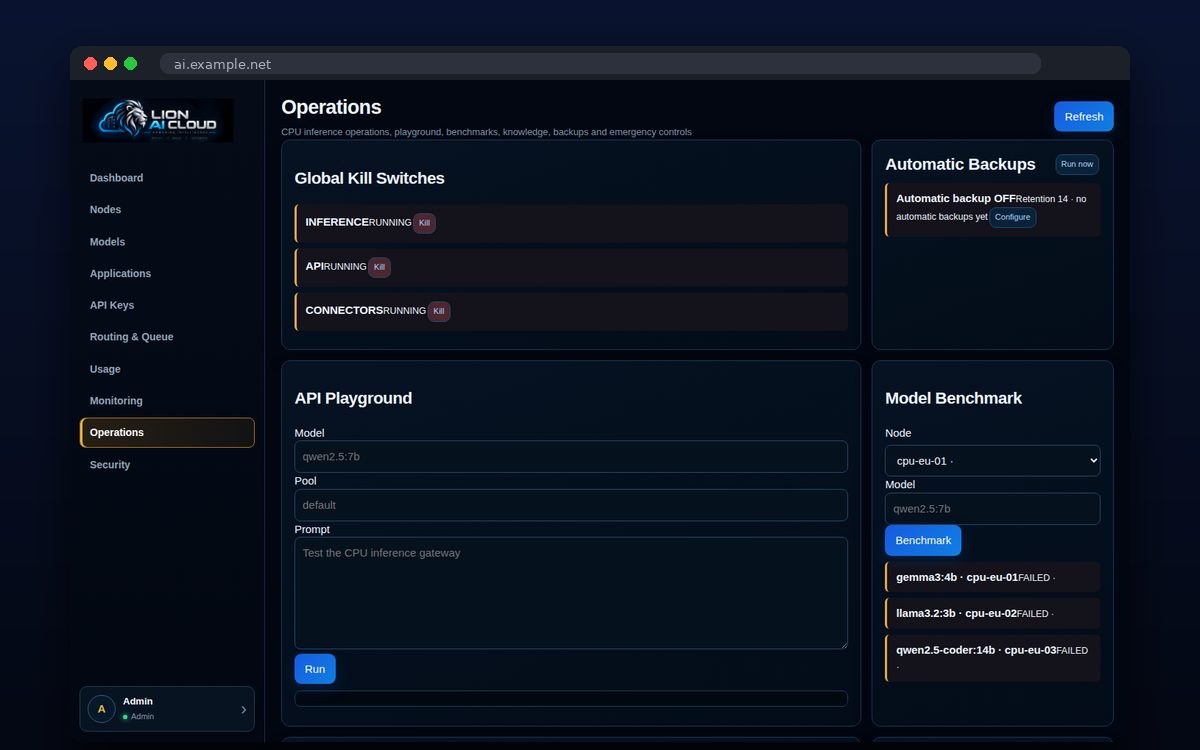
Each application gets its own API keys, requests-per-minute limit, monthly quota, allowed models and pools, its own system prompt and a separate knowledge base. Requests enter a queue with priority classes, so customer support never waits behind a batch job.

FEATURES

AI infrastructure under control

🖥️

Ollama & llama.cpp nodes

CPU, RAM and disk telemetry from a read-only agent.

🧠

Model manager

Pull, warm, delete and placement policies for models.

🔑

Per-app API keys

Limits, quotas and allowed models per application.

🚦

Priority queue

Background, batch, interactive, coding, support, critical.

⏱️

Benchmarks

Tokens/sec and latency history per node and model.

🛠️

Operations & security

Maintenance windows, config backups, alerts and a firewall.

Who it is for

FAQ

Frequently asked questions

Is a GPU required?

No. Lion AI Cloud is designed for CPU servers and also supports GPU nodes when available.

Which engines does it support?

Ollama and llama.cpp.

Where does the data stay?

On the servers you connect. Models run locally on your own nodes.

Tell me when it launches: Lion AI Cloud →